
01.07 / Build
Polar Brain.
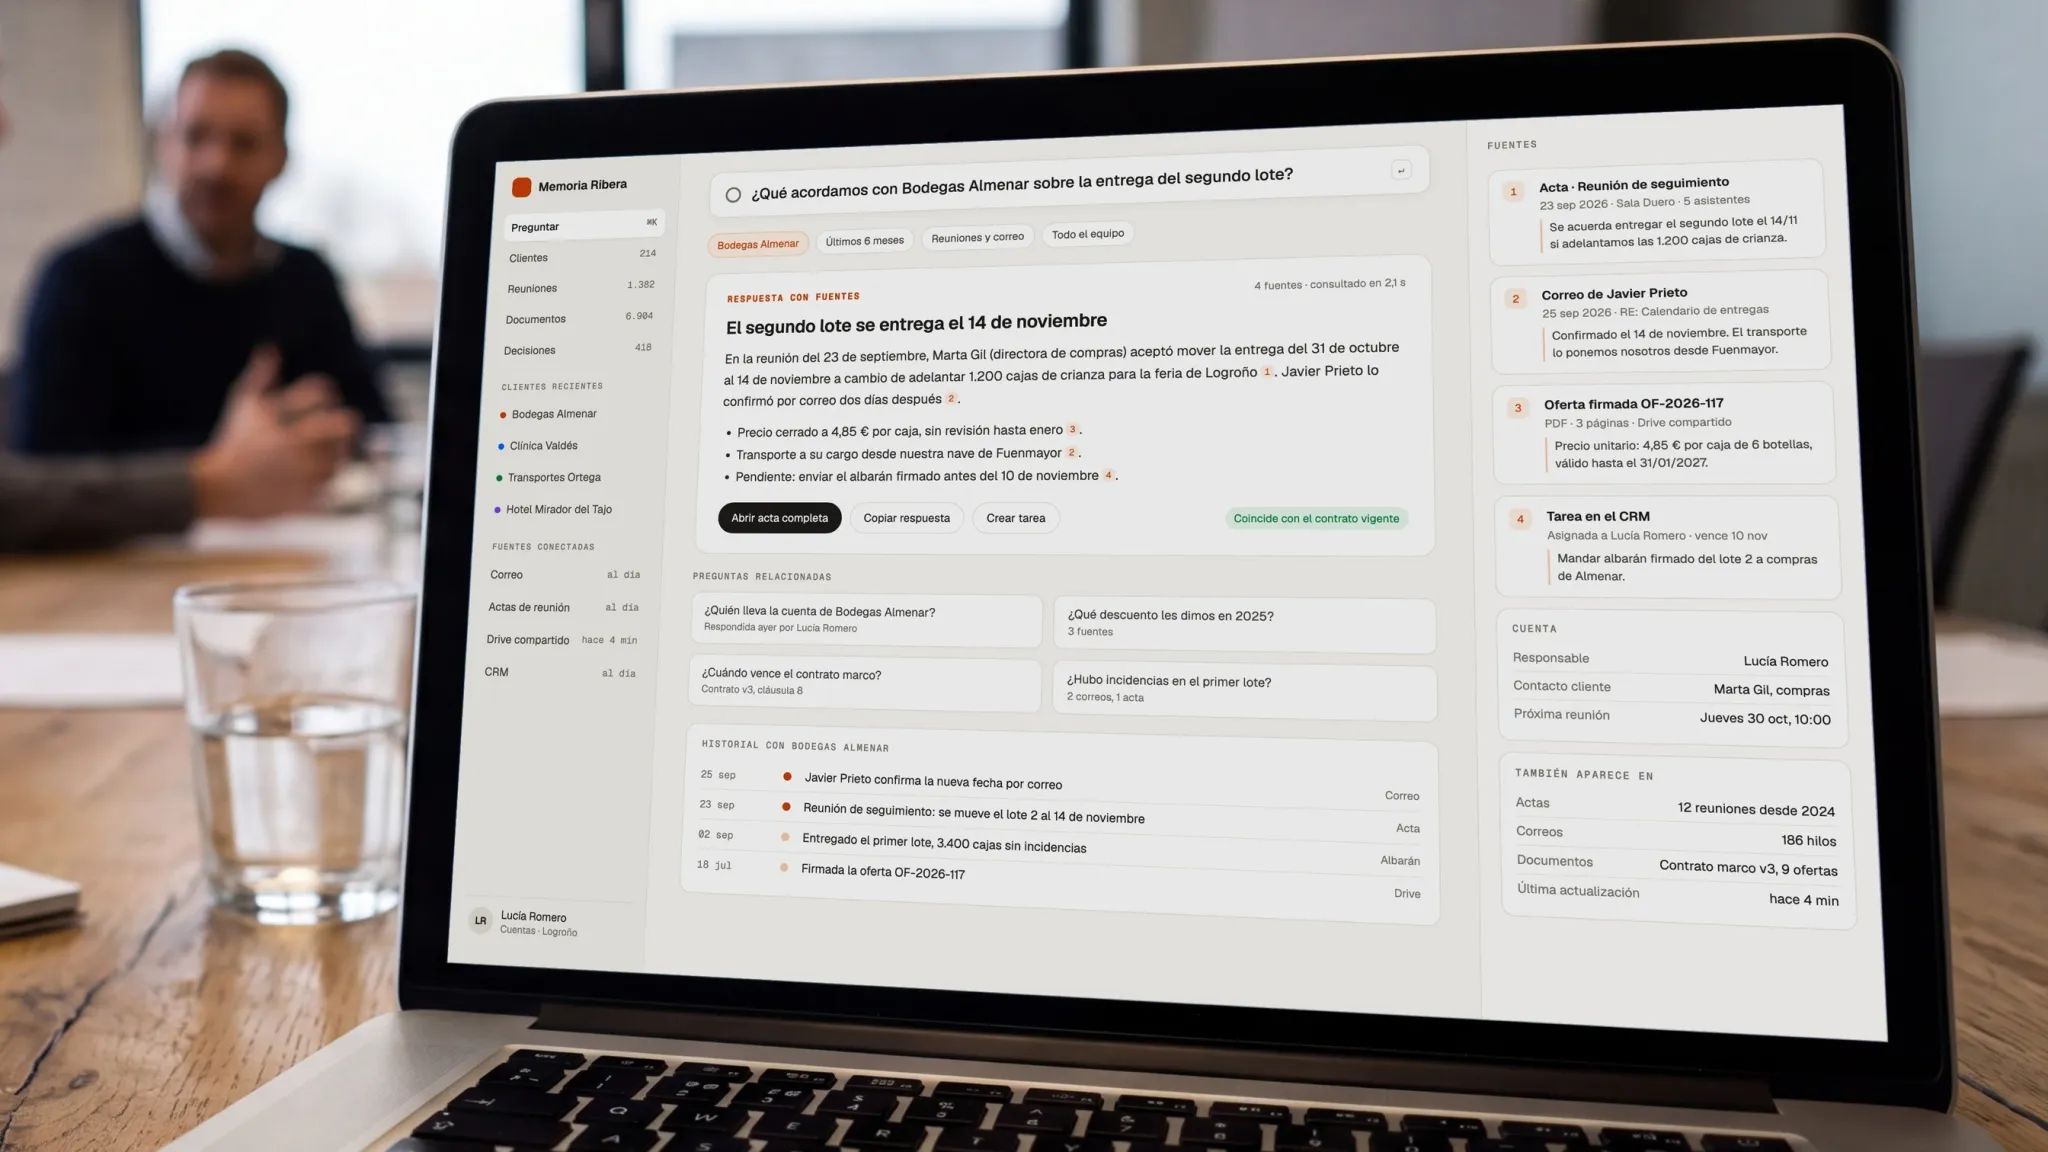
A memory for your company that survives the chat window. What gets decided is filed on the spot, searched by meaning and pulled back by the next session before it answers. Built inside your business and connected to the Claude your team already uses.
In detail
What you should know.
For example: 16 indexable URLs, Spanish and English. Hotel Talavera
What it is
Polar Brain is your company's memory, kept outside the chat. What gets decided is filed the moment it is decided, it is searched by meaning instead of by exact words, and the next session pulls it back before it answers. It connects to the Claude your team already uses, so nobody changes tool.
The same week, with and without a memory
Polargate builds it inside your business. It is a product implemented inside your company, not one you sign up for.
The problem it solves
Everyone works with Claude or ChatGPT now, and everyone runs out of context. Two hours into a conversation the window fills up. You open a new chat, explain it all again, and the model proposes the approach the team ruled out last week. Compacting does not fix it: it compresses the conversation instead of persisting it. A notes file does not fix it either, because nobody searches it by meaning and it never enters the session on its own.
Meanwhile the things the company actually knows, the price agreed, the architecture discarded, the mistake already made, live in the heads of three people.
The proof is our own brain
Polargate runs this on itself, every day, in production. Measured in September 2026:
The six layers between one client's knowledge and the shared library
- 2,864 knowledge chunks across 2,158 sources, 5.83 million characters.
- 599 new sources in the last 30 days.
- 8,463 MCP calls, every one of them audited.
- 507 sources stopped by the confidentiality wall before they reached the classifier.
- 284 lessons promoted to the shared library, 568 evaluated and discarded.
Those figures are the size of a corpus running in production, and nothing more. They are here because a memory system is only credible if someone is living inside it.
The confidentiality wall
This is the part that decides whether a company can use it at all. What belongs to one client does not leave that client. What is personal does not cross into client work.
Four independent layers
The rule is enforced four times over: a canonical SQL predicate, a TypeScript check with its own test in continuous integration, a table trigger that refuses the write at the point of writing, and a revalidation of each request. A failure in one layer does not open the door, and because part of it lives in the database, the protection survives a bad deploy.
What it does not do
There is no per-client encryption key and no physical isolation per tenant. Claiming otherwise would be easy and false.
What goes into it
Three ways in: by hand from the chat or the panel while you work, automatically from real mail, and on demand by uploading documents.
It reads PDF, with OCR when the PDF is a photograph of a page, Word, web pages, mail from Gmail and Microsoft 365, and meeting transcripts. Everything is deduplicated by hash, with a ceiling of 20 MB per file. Measured in our own corpus: 172 documents, 40 emails, 18 meetings.
This runs on discipline. If nothing is filed, there is no brain. The habit is small, read before you form an opinion and file when you finish, and it is the whole difference.
How it is searched
By meaning, over embeddings of 3,072 dimensions in Postgres. There is a minimum relevance floor, and that floor is exactly what lets the answer be "I do not know" instead of an answer assembled from noise.
The model has two levels: the entity, which is the account, and the project, which is a piece of work inside it. Knowledge filed without a project is shared canon of the entity and every project inherits it. A search inside a project returns that project's sources plus that shared canon. Projects do not link to each other by default: separate by default, connected on demand.
Today this is vector search. It is not hybrid and there is no reranking. We would rather write that down than let you assume it.
The shared library
A generic lesson learned in one project is anonymised automatically and served inside anyone else's search, without the client data travelling with it. The redaction strips names of people, companies, clients and projects, along with figures, credentials, URLs and email addresses. When the classifier is not confident, it does not promote: losing a lesson is cheaper than leaking one.
Measured: 284 lessons promoted, 568 evaluated and rejected, 31 dropped as duplicates, 1 rejected because it carried personal data.
Why it exists at all: a deployment error that cost hours in one project was already written down in another project's brain, locked inside its silo. The shared library is what stops the same mistake being paid for twice.
Connecting it to the Claude you already use
The brain is exposed over MCP, with our own OAuth. There are no keys to paste by hand: the client registers dynamically, so connecting an account is a URL and a login. Once connected there are 125 tools, and every call is written to the audit log.
Access is locked by role. An outside guest can invoke a subset, five tools today, and the tool list itself is filtered, so the rest is not even visible. A guest's searches do not get the shared library folded in, because that library is distilled from work with everyone else. Revoking access takes effect mid-session: membership deleted, pending invitations void, unredeemed codes gone, tokens revoked.
The visual console
Retrieval is invisible by nature, which makes it hard to trust. The console turns it into something you can look at: a graph of entities and projects, a search box per entity, knowledge by category, and document upload with a status per file. It is protected by role, and it is what we show in a demo.
For a company or for one person
For a company: several entities and projects, roles, an audit trail of every call, a ceiling of 200 AI calls per user per day, and rate limits per entity. It fits consultancies with several clients, professional firms, and any team where the knowledge lives in two people's heads.
For one person: the same product without the multi tenant part. One brain, with the same wall between what is personal and what is professional. It is not an afterthought. The heaviest real use of this system today is exactly that.
The limits
Time
The hard one is the time axis. In our own retrieval lab, the question about which price is valid now failed in all four configurations we tested, and every one of them returned the old price. The problem is knowing what is true today, and retrieval does not solve that. So state that has to be exact, tickets, dates, orders, hours consumed, is read deterministically from the database and never inferred from vectors. Vectors are for fuzzy knowledge.
What is not deployed
Hybrid search, reranking and a temporal knowledge graph are studied and parked, not running. We do not claim a security certification either. What we can show is the architecture, the tests in continuous integration and the audit log.
What you get
What you take away.
Everything is written down before we start, and everything stays in accounts your company owns.
01Deliverables
- 01
A company brain built inside your own business, with the entity and project model that keeps accounts and engagements apart
- 02
A confidentiality wall enforced in four independent layers, one of them inside the database so it survives a bad deploy
- 03
Ingest of what you already have: PDF with OCR when the file is a photo, Word, web pages, Gmail and Microsoft 365 mail, meeting transcripts, deduplicated by hash
- 04
Search by meaning with a minimum relevance floor, so the answer can be "I do not know" instead of noise
- 05
A shared library that anonymises generic lessons automatically and serves them inside every other search, without client data travelling
- 06
MCP connector for the Claude your team already uses, with our own OAuth and dynamic registration, so there are no keys to paste by hand
- 07
Role-based tool lock: an outside guest sees only the subset you allow, and never gets the shared library folded into their searches
- 08
A visual console with the entity graph, search per entity, knowledge by category and document upload with a status per file
- 09
Engines that keep the knowledge alive: contact cards, market watch per active project, and expiry of what stopped being true
- 10
Audit log of every call, a ceiling on AI spend per user per day and rate limits per entity
02How it runs
- 01 · Week 1 to 2
Discovery Sprint
Interviews with the people who will use the thing, an audit of the systems you already run, a data model, an architecture decision and a scope written in plain language. It ends with a fixed price and a delivery plan, and the document is yours whether or not you continue.
- 02 · Week 2 to 4
Foundations
Design direction, database schema with row level security from the first migration, environments, continuous integration and the first screens in a place you can open. Nothing is built on a platform you cannot leave: the repository, the backend and the hosting are created in your accounts.
- 03 · Week 4 to 8
Build to the first shipped iteration
Weekly deployments, a short written update with each one and a running list of decisions. The goal of this stage is a version in production with real data where someone can finish an actual task, not a demo. Scope changes are priced before they are built.
- 04 · Week 8 onwards
Audit, launch and handover
Several review passes over correctness, architecture, accessibility, performance and security, with every finding checked by a second reviewer before it counts as real. Then the launch, the handover pack and, if you want it, a move to the CARE retainer for maintenance and evolution.
For example: 536/536 translation keys present in each of the three languages. Estepona Golf
Who it is for
We don't take every project.
We would rather tell you now than halfway through. If you recognise yourself on the left, let's talk.
It fits if
- You need a website, a portal or an app that does not exist yet, or one that has run out of road
- You want the code, the data and the hosting in accounts your company owns
- You prefer a fixed price before work starts to an open hourly bill
- Someone on your side can decide and give the project a few hours a week
- You care that Google and AI assistants can read it from day one
It is not for you if
- You are after a cheap template or a site put together over a weekend
- You want it to live on a platform you cannot leave later
- Nobody on your side can review screens or make decisions
- You need people to bill hours without a clear goal
For example: 2 languages live on the site, Spanish and English. Global Dynamic Security Group
Timing and budget
How we quote.
No price list and no hourly billing during a build. After a short call you get a written quote for your project.
- Timeline
- Connecting an account to Claude takes minutes: dynamic registration means it is a URL and a login, with no keys to paste. The corpus is what takes time. Polargate agrees the plan per engagement after looking at how much history there is to ingest and which mailboxes, drives and documents connect. The value does not appear on day one. It appears once the corpus has volume and the team has the habit of filing as it works.
- Team
- Andrés Ciordia, Chief AI Officer, leads the company brain. Our team connects your sources and builds it into the tools you use, and Pedro Ciordia, CTO, sets the architecture and reviews it before it goes live. The brain described here is the one we run our own company on, every day, which is why the figures on this page are measured and not projected.
- How the price is set
- Fixed price per engagement, in a private quote after a first call. It depends on the history to ingest and the systems to connect, and there is no published hourly rate.
- The stack
- SupabaseReactVite
For example: 38 Spanish and English routes prerendered as static HTML. Santo Domingo Bay
Work
Work in this line.
Real projects. Open each one to see what we built and the figures we measured.
Hotel Talavera
Hotels and hospitalityA bilingual hotel website that crawlers and AI assistants can read
27 published FAQs with FAQPage schema
BuildGrowCare
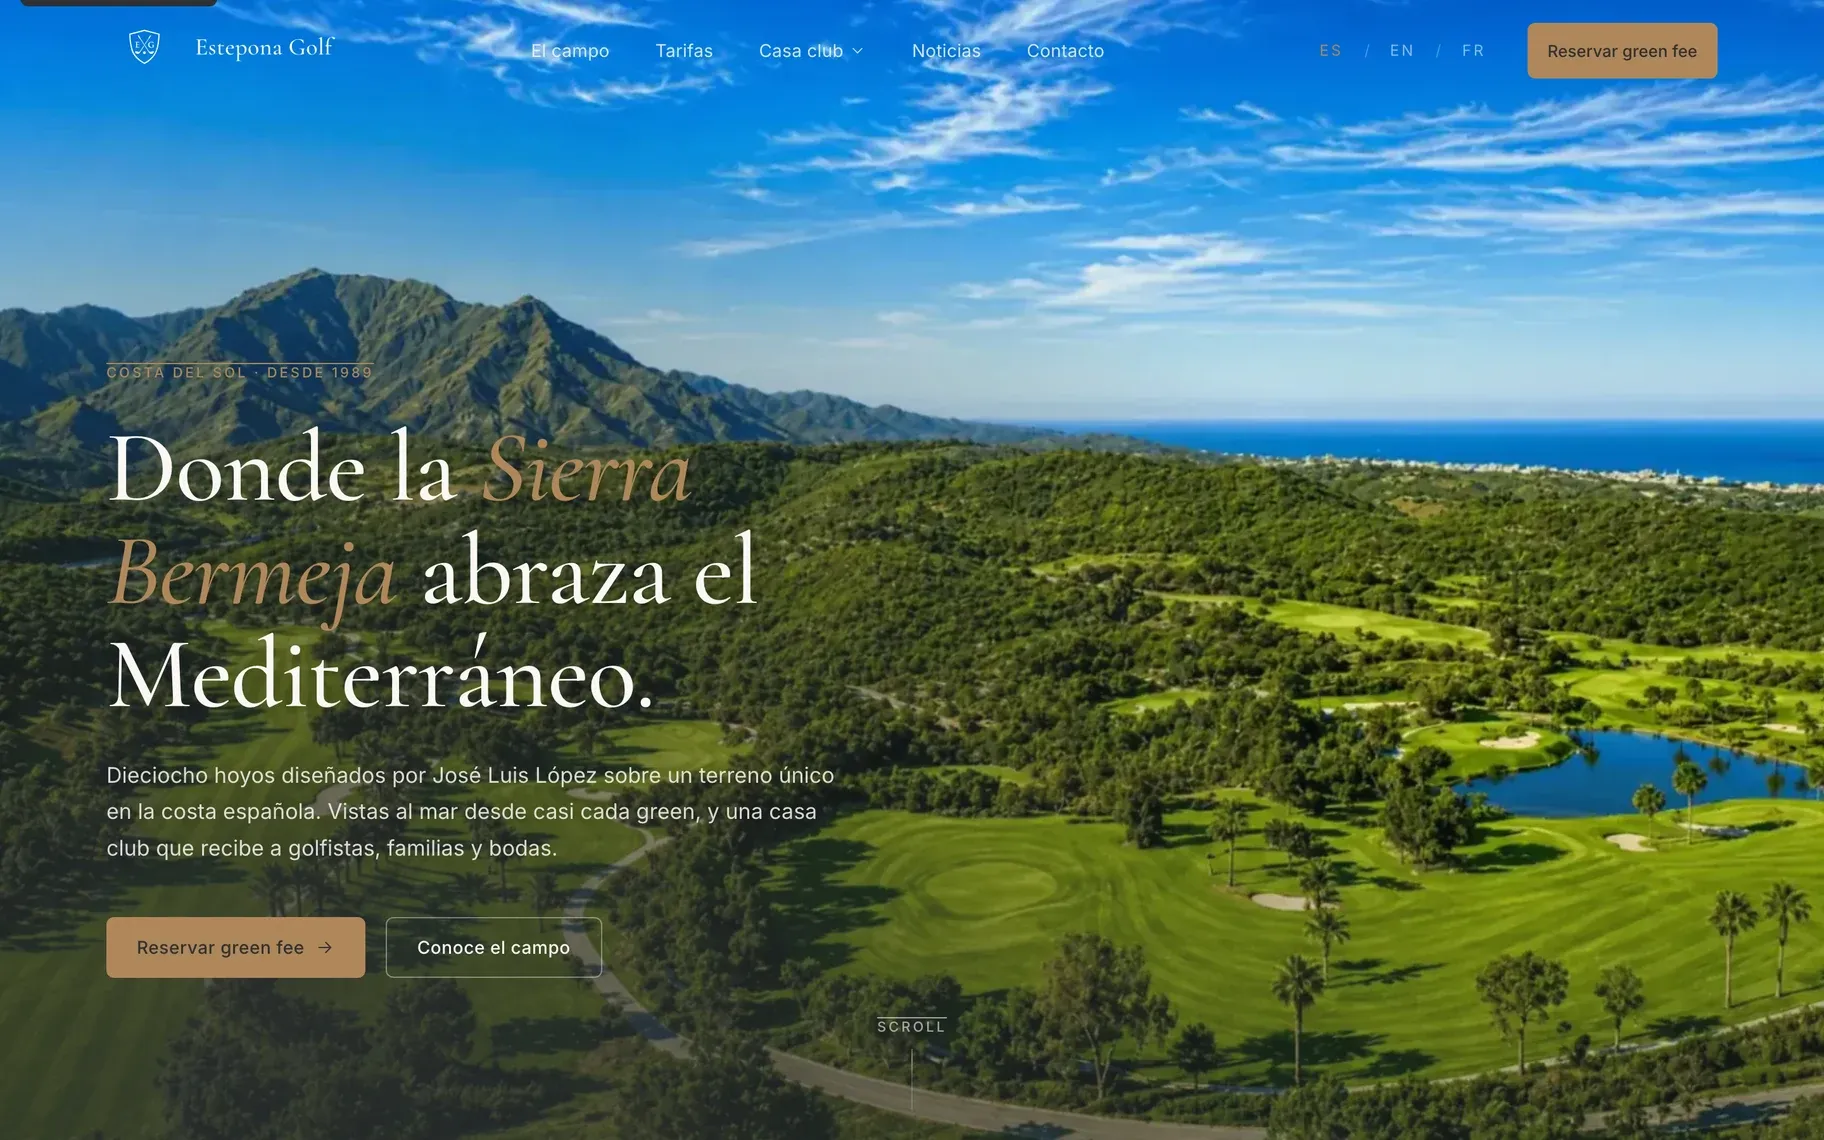
Estepona Golf
Golf and leisure, Costa del Sol tourismA website in three languages for Estepona Golf
251 KB hero image weight, down from 1.3 MB
BuildCare
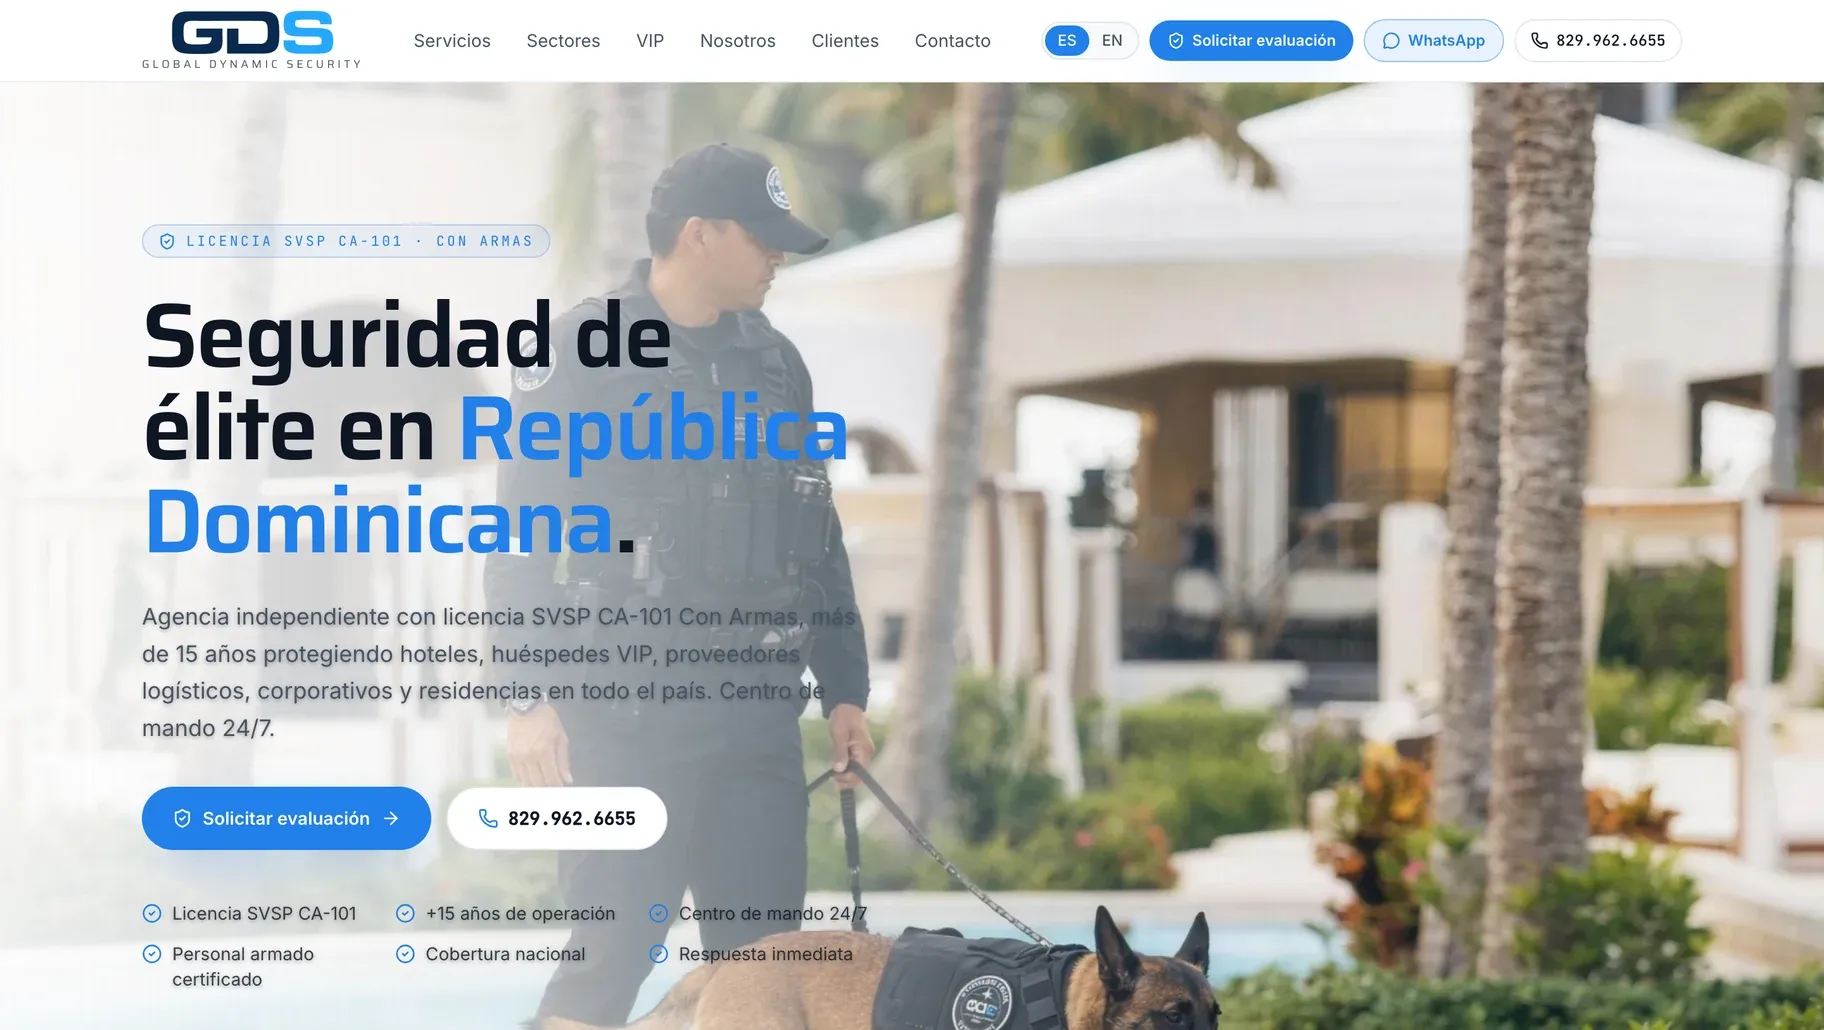
Global Dynamic Security Group
Private security services, Dominican RepublicBrand and bilingual site for Global Dynamic Security Group
15 pages in the brand identity manual
Build
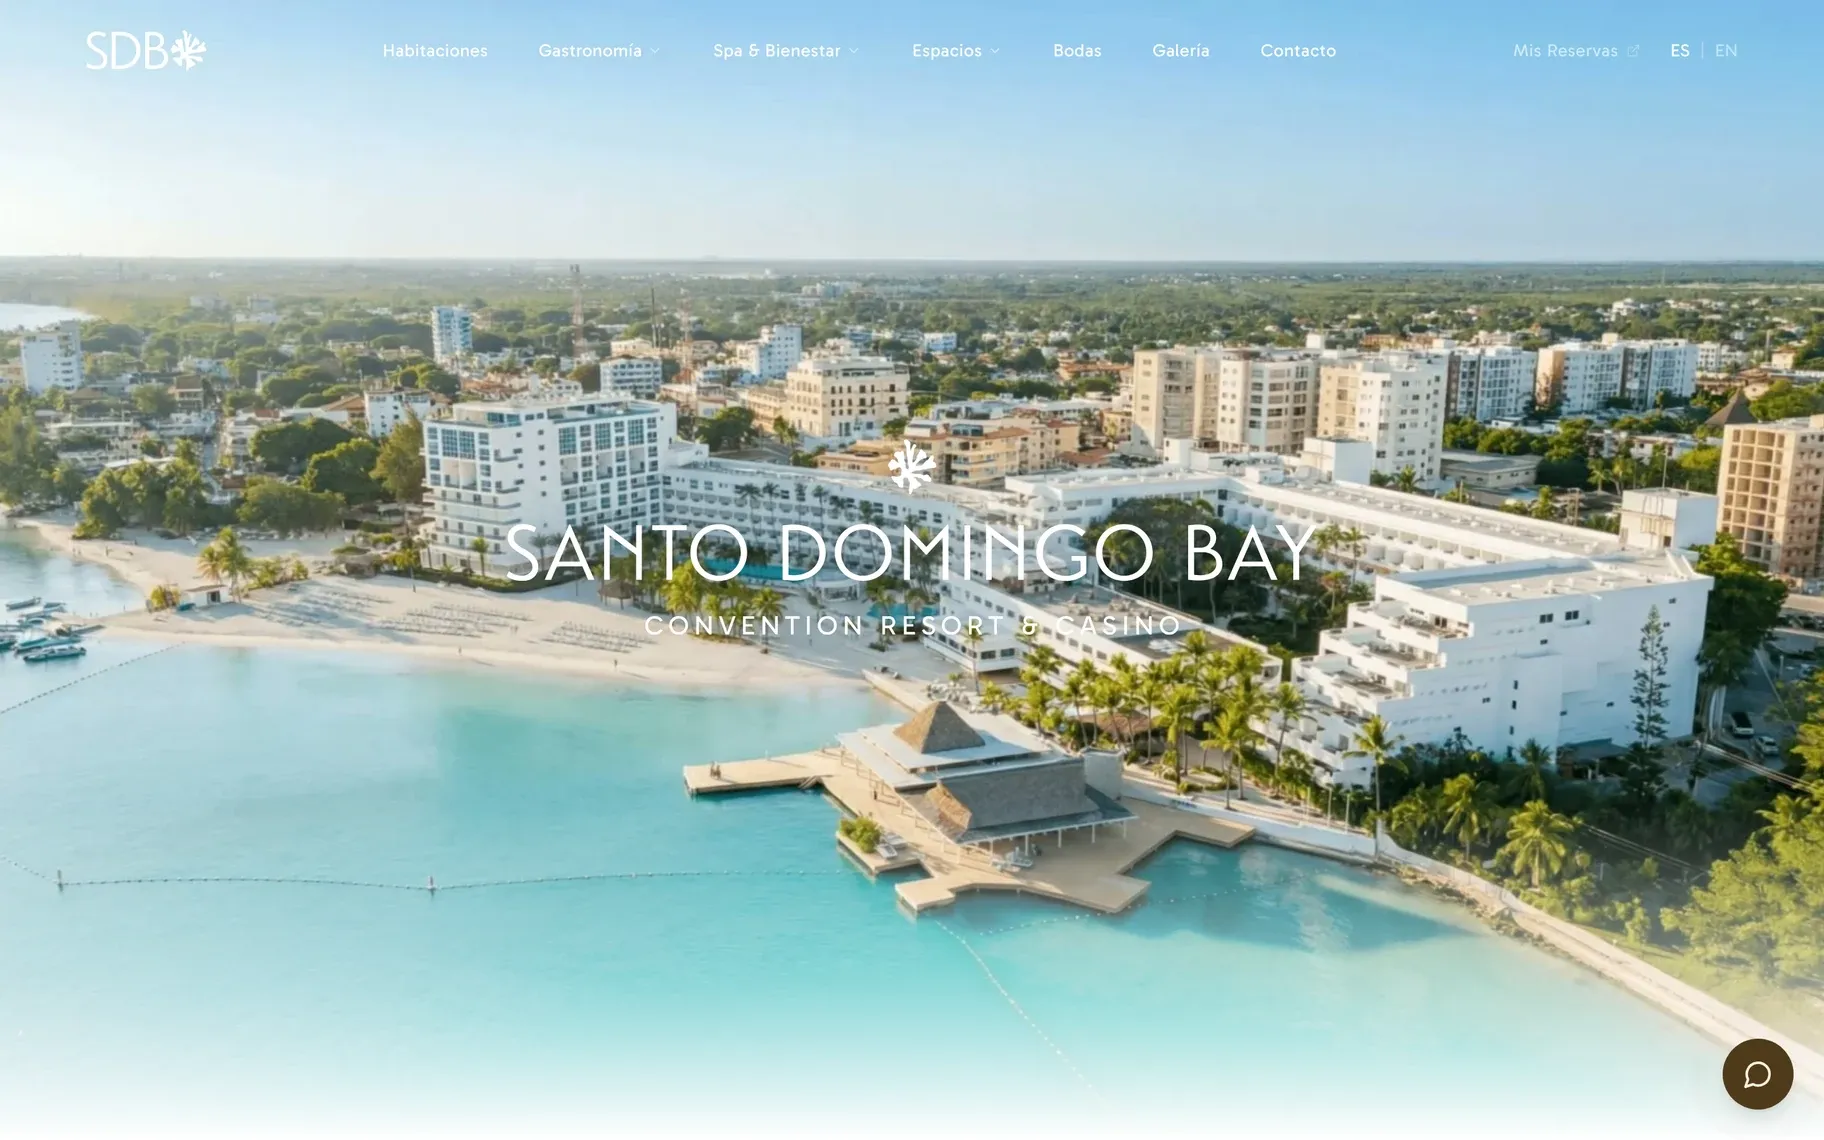
Santo Domingo Bay
Hospitality: convention resort, casino and private beachWe rebuilt a Caribbean resort's website as static HTML
5 valid rich result items on the home page in Google's test
BuildGrowCare
Globalia
Travel and tourismThe corporate web platform of Globalia
11,421 characters of real content an AI crawler gets from a news page
BuildGrow
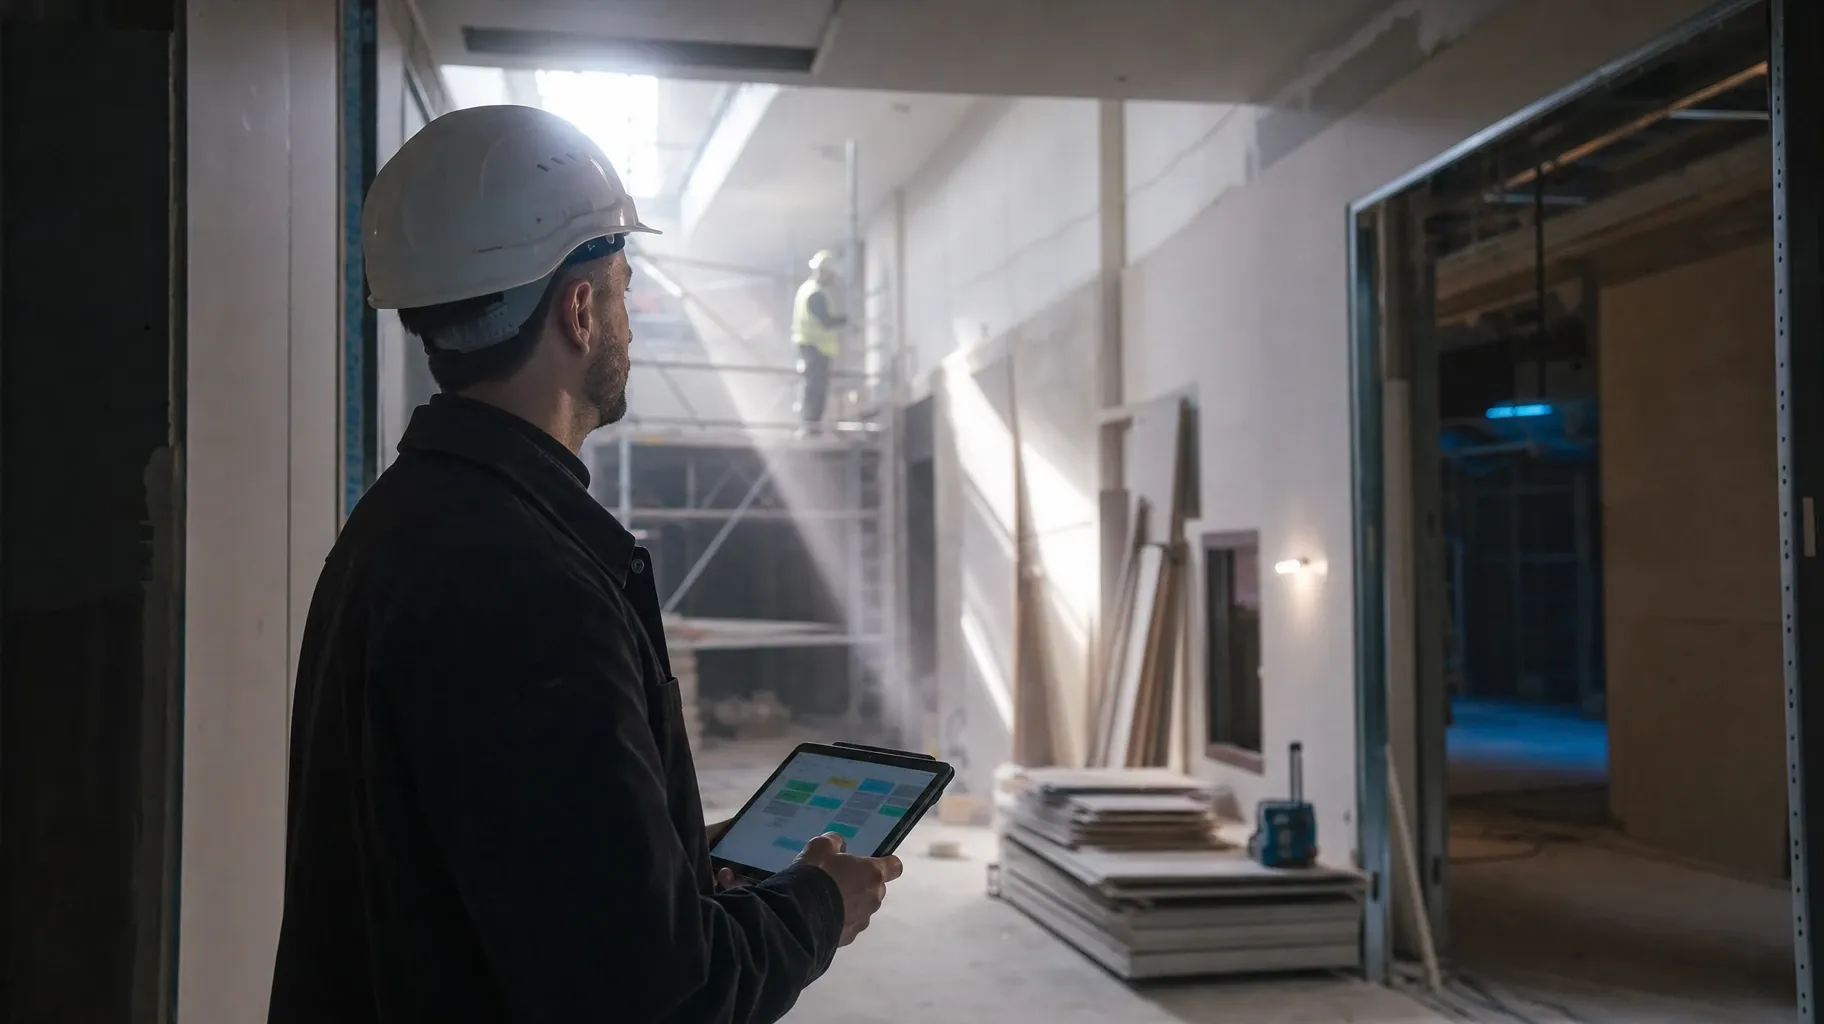
Elite Smart Build
Construction and hotel refurbishmentA custom operating system for Elite Smart Build
23 Postgres tables with row-level security forced
BuildCare
For example: 11 modules delivered in Phase 1. Elite Smart Build
Same line
Other services in Build.
Each service has its own page with what it includes, the usual timeline and the projects where we did it.
- 01WebsitesWebsites that Google and AI assistants read as well as people do.
- 02AI features and agentsAssistants that answer with your company's own data.
- 03Web apps and internal portalsYour operations, out of the spreadsheet and into a real application.
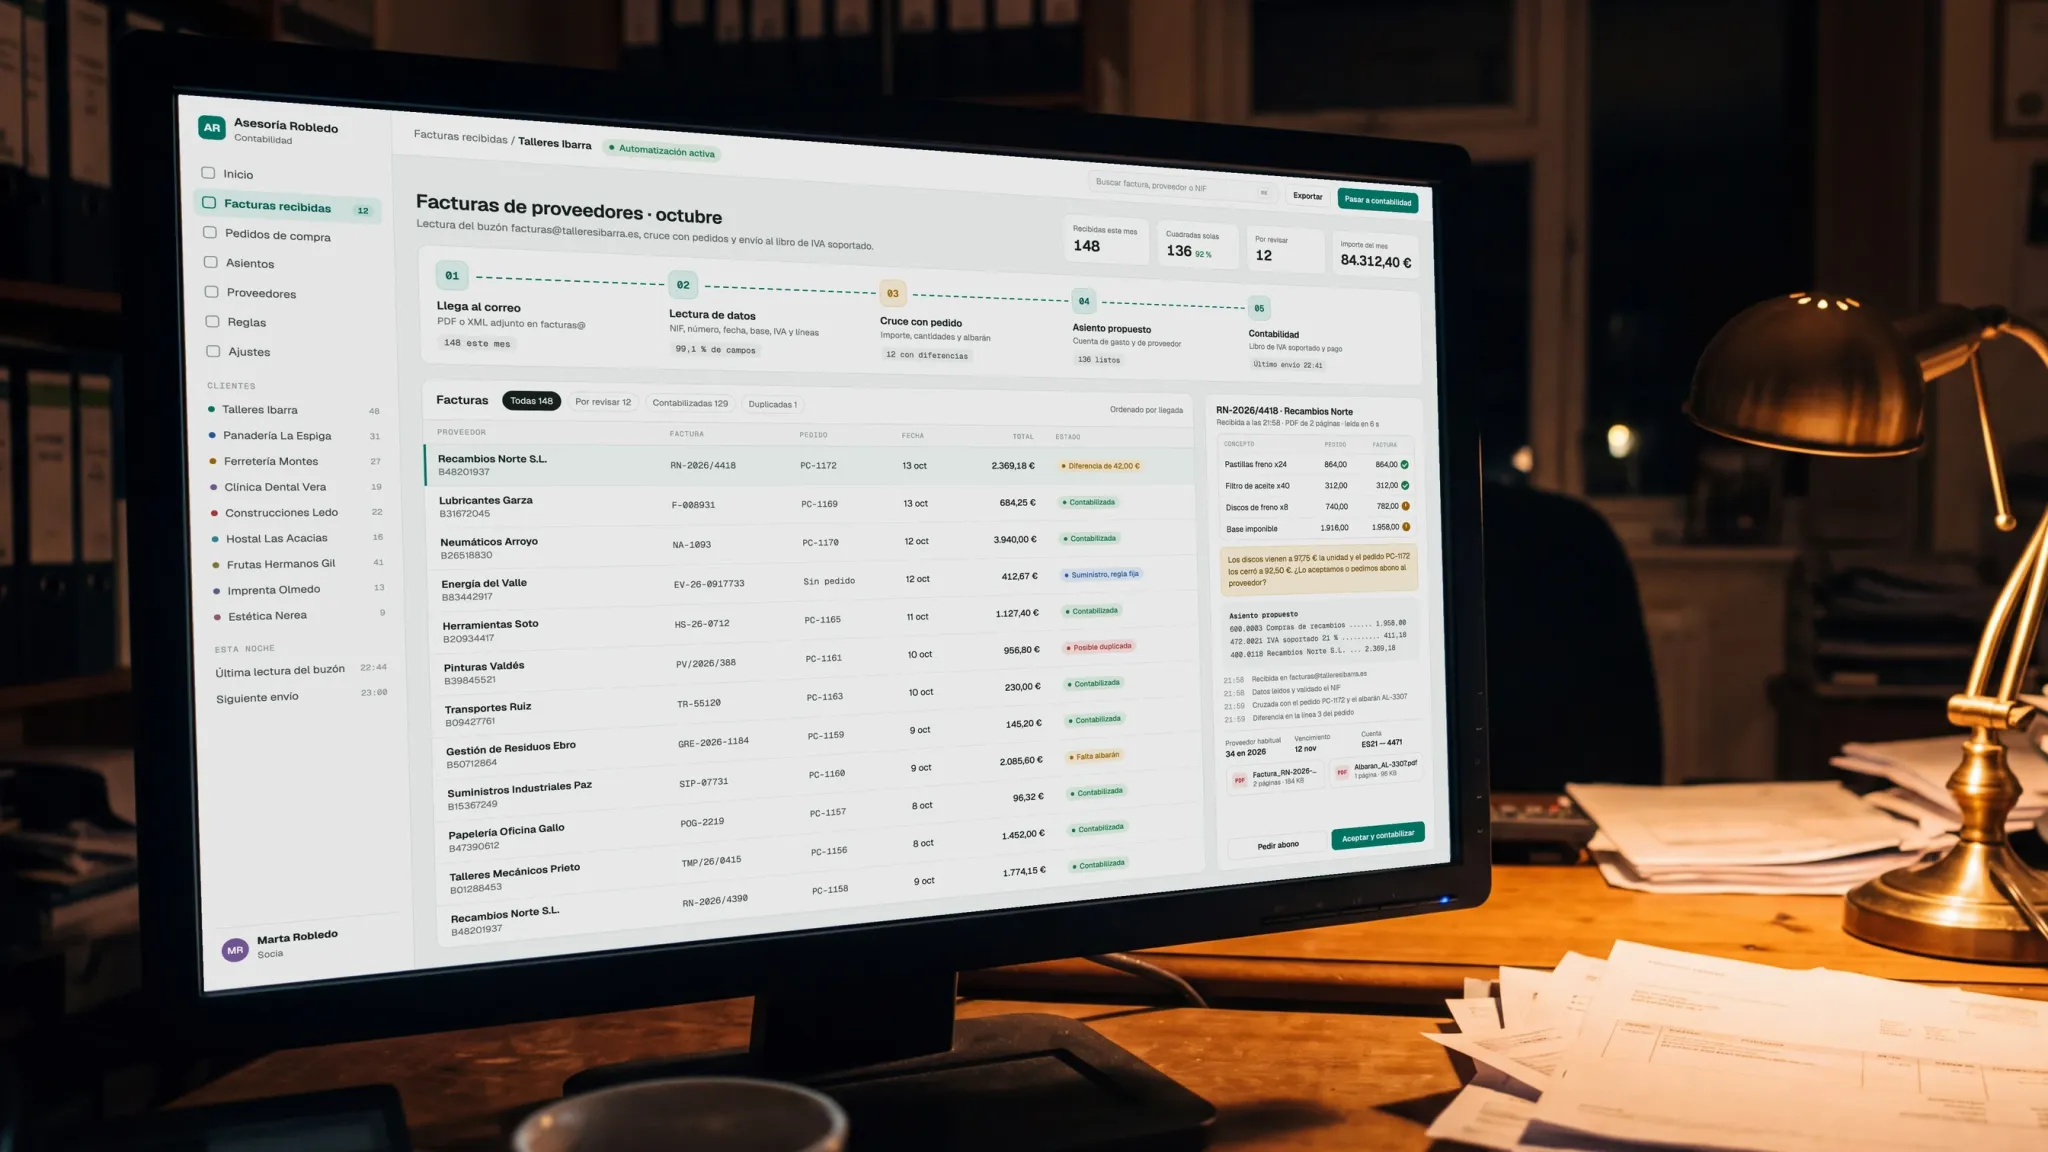
- 04Integrations and automationYour systems talk to each other.
- 05Mobile appsAn app for iOS and Android that updates in minutes.
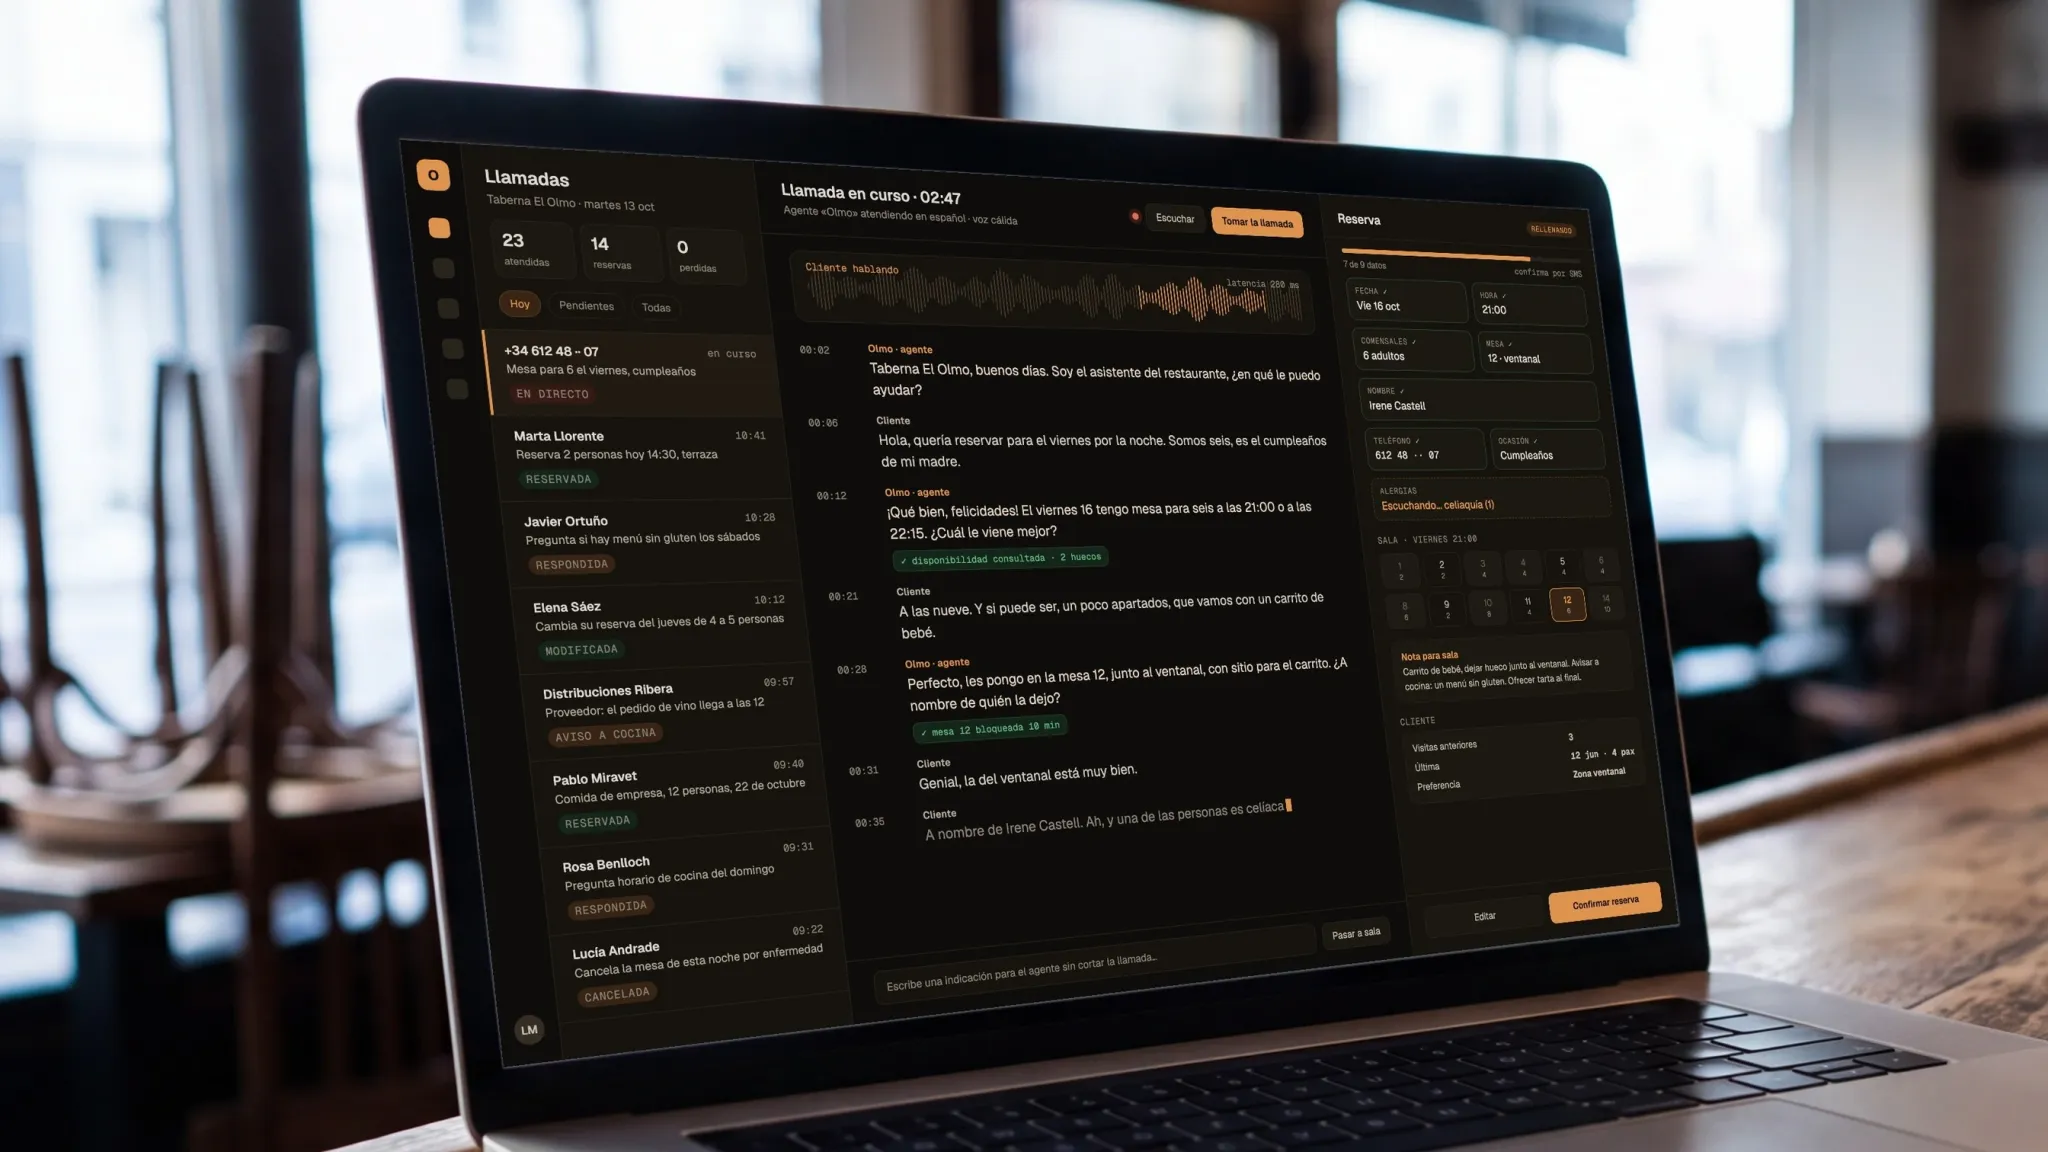
- 06Real-time voice agentsVoice agents that take the order and make the booking.
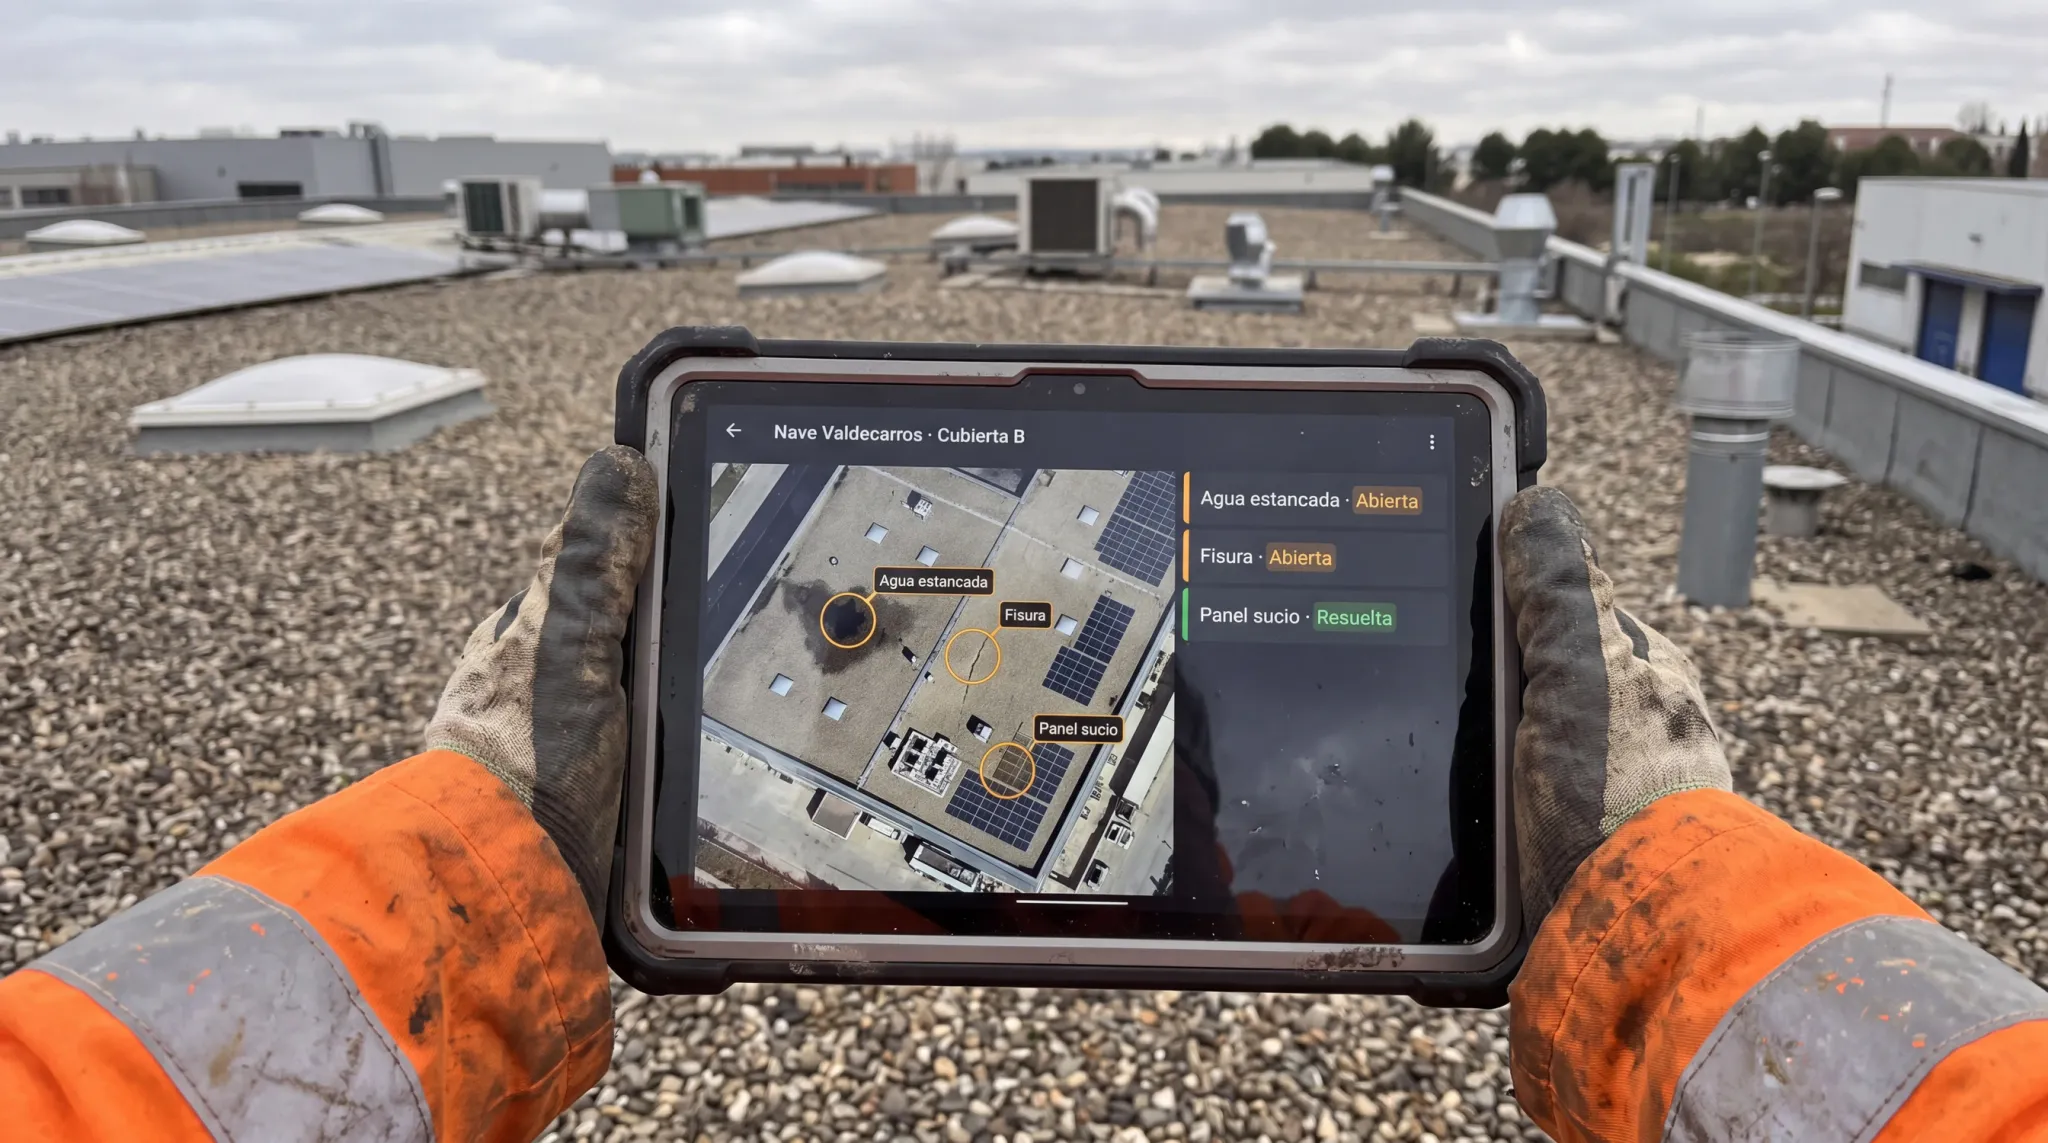
- 08Camera, drone and building softwareThe software layer over the cameras, sensors and drones you already have. The hardware is not ours.
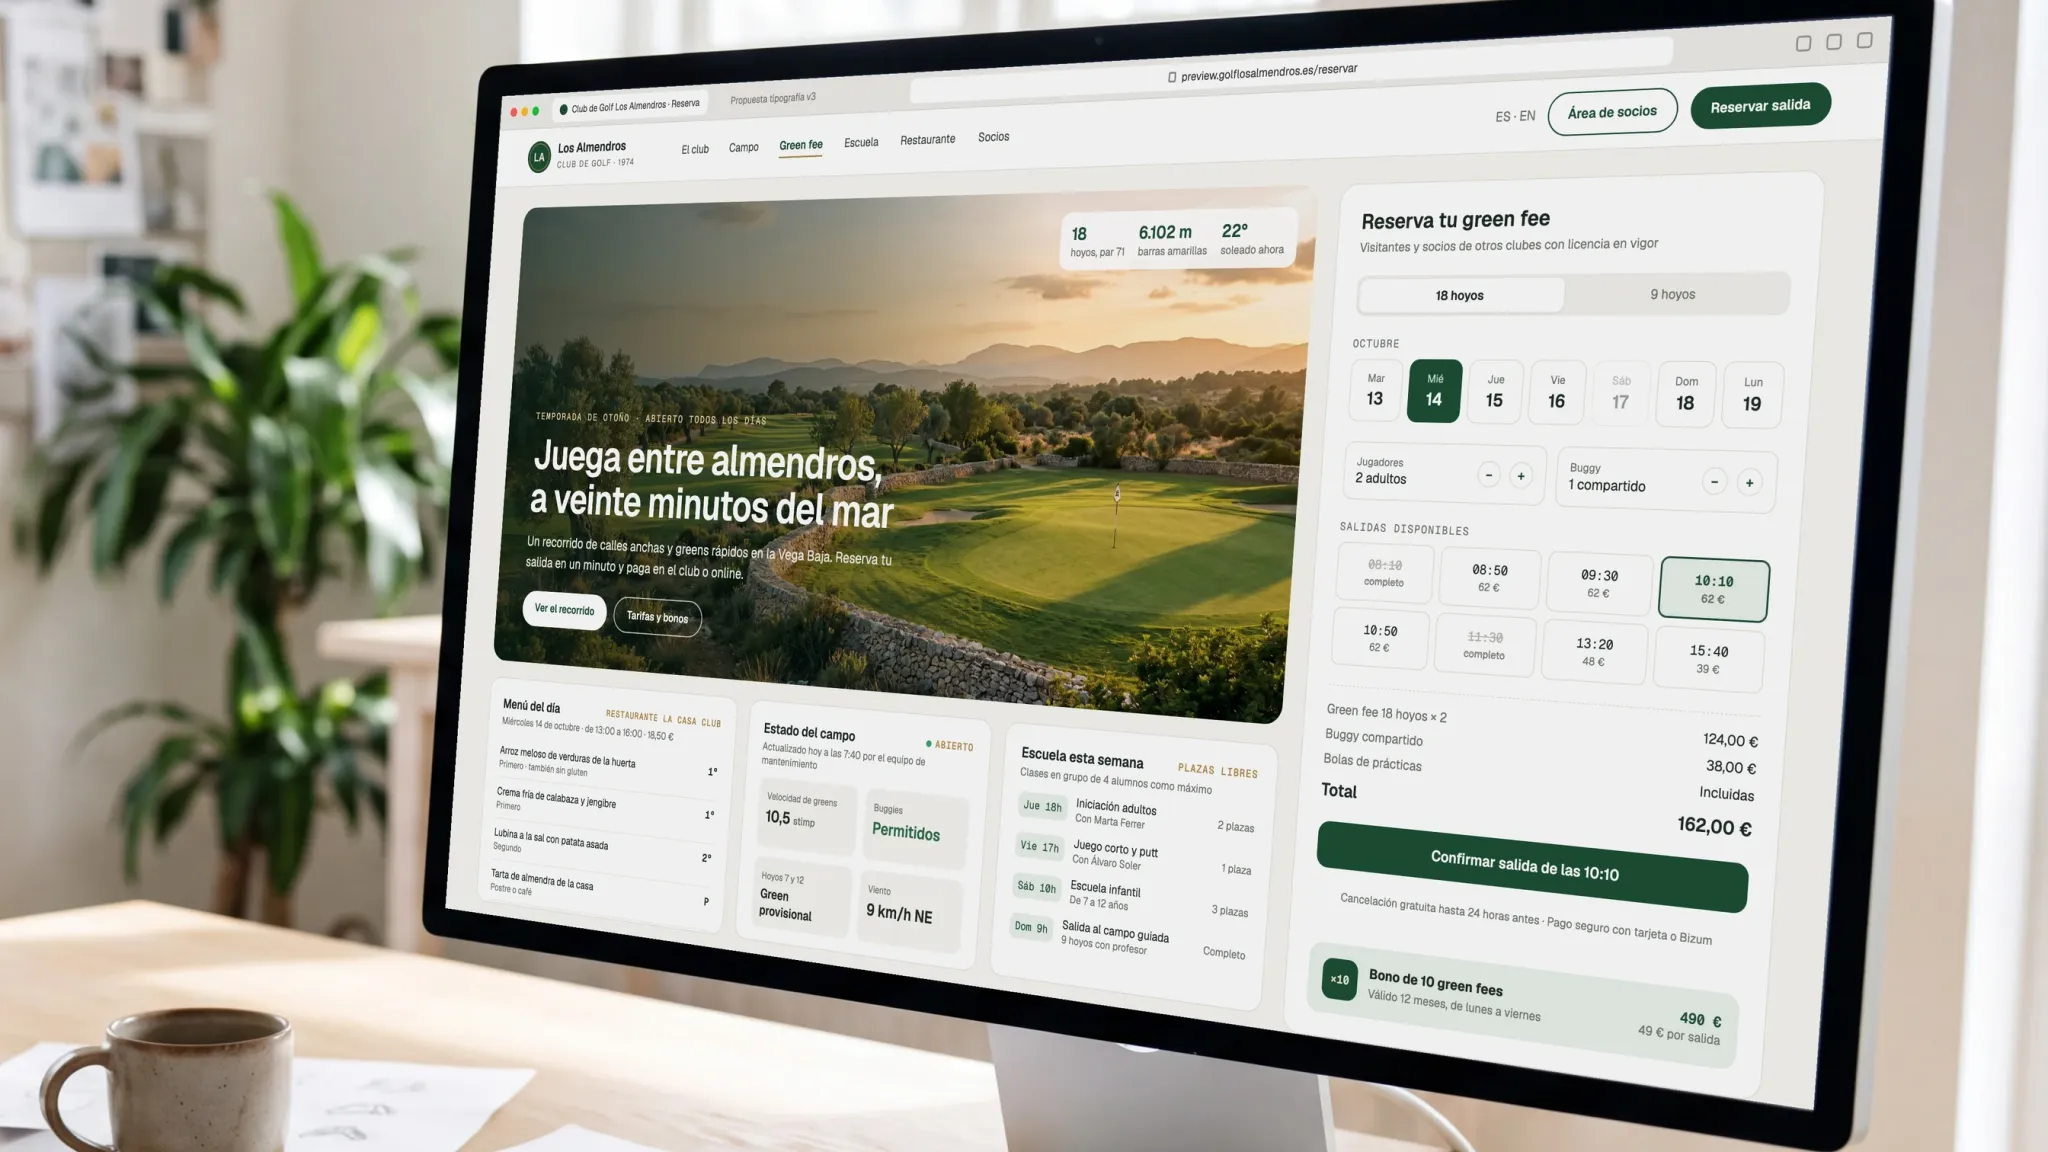
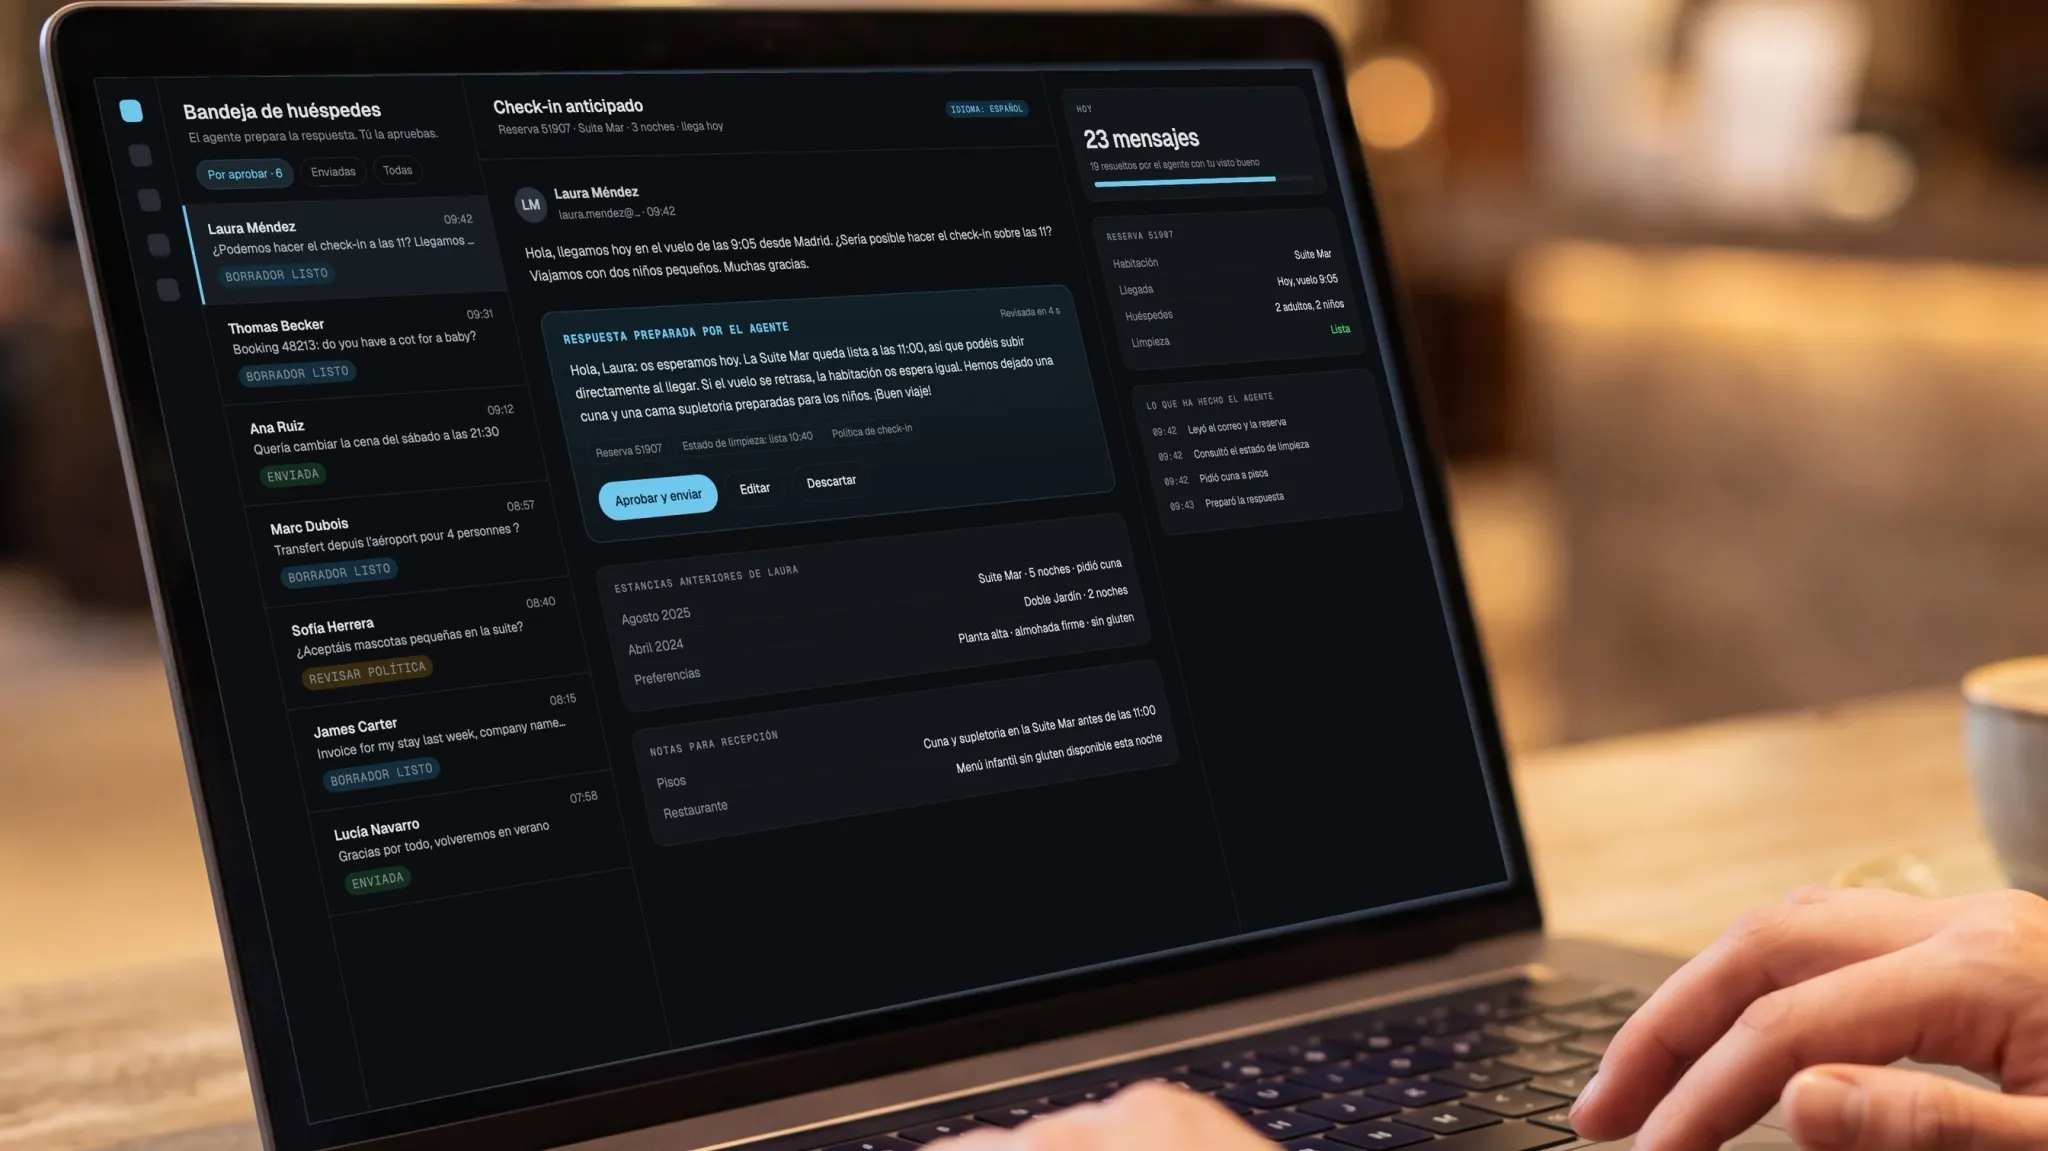
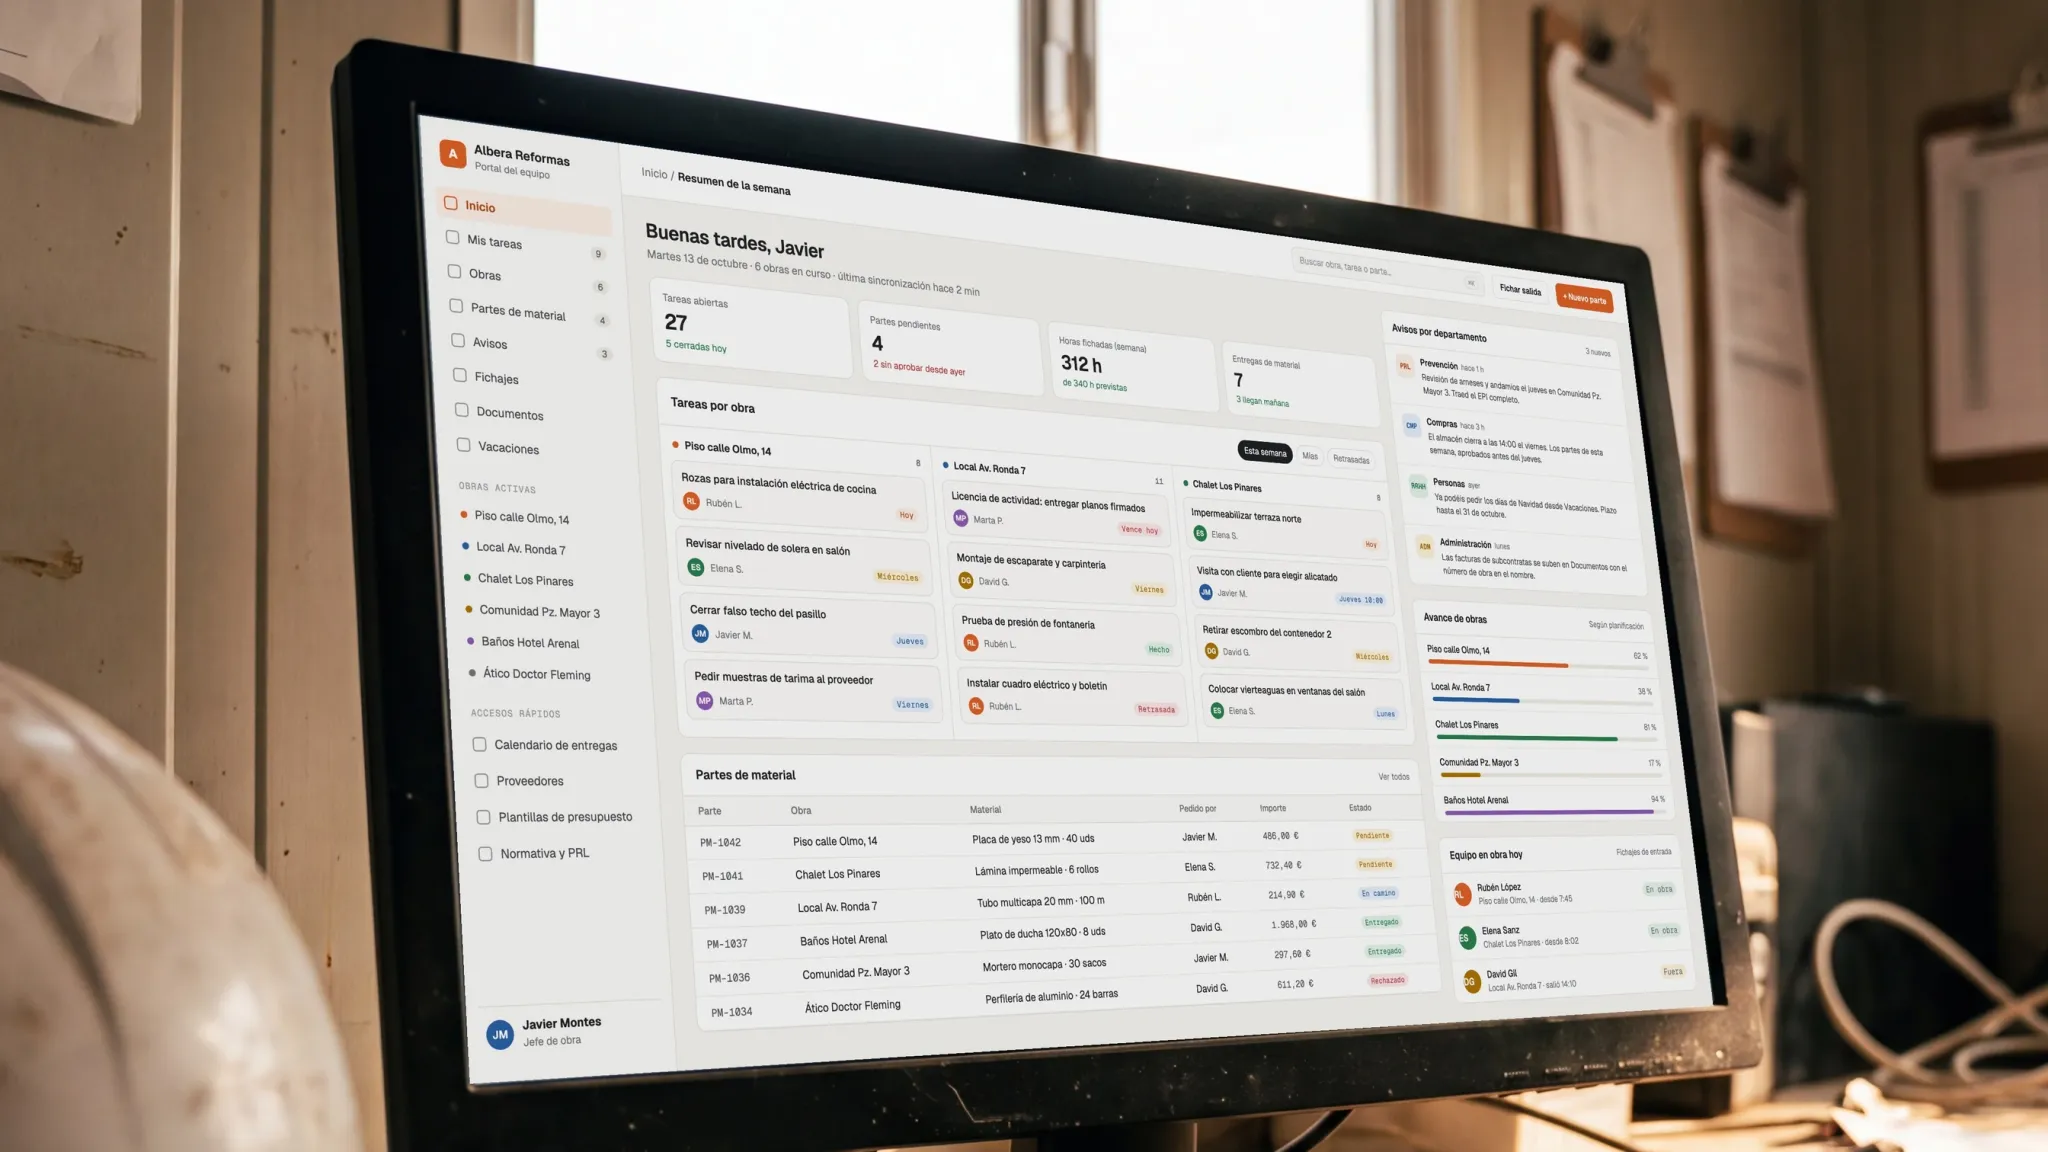
For example: 27 published FAQs with FAQPage schema. Hotel Talavera
FAQ
What people ask us.
What is a company brain?
Can one client's information end up in an answer about another client?
Does it work with the Claude we already use?
Is this only for companies, or can one person have a brain?
How is this different from uploading documents to a chatbot?
For example: 251 KB hero image weight, down from 1.3 MB. Estepona Golf
Get started
Tell us what you want to build.
Websites, apps, custom systems and AI for companies that need them in production in weeks. Fill in the form or book a 30 minute call: a senior engineer answers within 48 business hours with a first take on scope, timeline and price.
First step
Two weeks to close scope, architecture and price before anything is built.
No price list. You get a private quote, in writing, after a short call.
Then, to build, always at a fixed price
Not ready yet?
- AI visibility auditOne-off, fixed price.